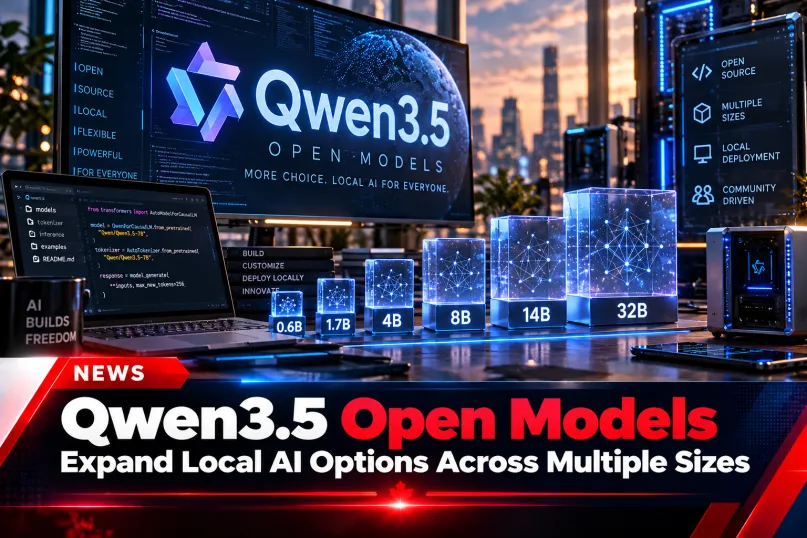
Alibaba’s Qwen team expanded the Qwen3.5 model family in early 2026, releasing a range of open-weight multimodal models that can be downloaded and run locally when users have suitable hardware.
The family spans very different size classes. Official Qwen repositories include compact 0.8B, 2B, 4B and 9B models as well as larger 27B, 35B-A3B, 122B-A10B and 397B-A17B variants. That makes “runs on a personal computer” highly dependent on which model, precision and quantization format is used.
Qwen3.5 includes both dense and mixture-of-experts models
Some Qwen3.5 variants use a mixture-of-experts architecture. For example, Qwen3.5-35B-A3B has roughly 35 billion total parameters while activating only a smaller subset for each token. Qwen3.5-122B-A10B follows the same general approach at a larger scale.
This design can reduce the amount of computation used per generated token compared with activating every parameter in a similarly sized dense model, although memory requirements can still be substantial because model weights must remain accessible.
Which Qwen3.5 models are realistic for local use?
The smallest 0.8B, 2B, 4B and 9B variants are the most practical starting points for ordinary desktops, laptops and compact AI systems, especially when quantized versions are used.
The 27B and 35B-A3B models can also be used locally on more capable workstations, but memory requirements vary significantly with precision, context length and inference software. Large variants such as 122B-A10B require substantially more memory and should not be described as universally suitable for consumer PCs.
Quantization can reduce memory usage by storing model weights at lower precision, but the trade-off can include changes in speed, output quality or compatibility depending on the format and runtime.
Official benchmarks show strong results, but they are not independent tests
Qwen’s model cards publish benchmark comparisons against models including GPT-5-mini and other open and proprietary systems. On several knowledge, reasoning, coding and instruction-following benchmarks, Qwen3.5 variants score competitively.
Those tables are useful reference data, but they are published by the Qwen team itself. They should therefore be described as official benchmark results rather than independent validation. Real-world performance can vary with prompts, inference settings, quantization and workload.
Open weights broaden deployment choices
Qwen3.5 models are distributed through Qwen’s official Hugging Face collection and related model repositories. Open-weight availability allows developers to inspect deployment requirements, run supported models on their own infrastructure and build applications without sending every request to a hosted API.
That can be useful for privacy-sensitive workflows, offline experimentation, cost control and customized inference environments, provided the selected model fits the available hardware.
What developers should check before downloading a model
Model size alone is not enough to determine whether a system can run Qwen3.5 comfortably. Developers should check VRAM or system RAM, supported quantization formats, context length, inference framework compatibility and expected throughput.
A smaller quantized model may be more useful on a personal workstation than a much larger model that technically loads but runs too slowly for practical use.